
Vehicular Health Monitoring Digital Twin PoC
ICANIO built an AI-powered healthcare record digitization platform that cut manual data entry by 60% and improved patient record accessibility 4x.
27 Sep 2026
Most enterprise AI programs do not die in a dramatic failure. They die quietly, a few months after a successful pilot, when the model that impressed everyone in a demo never quite makes it into the systems people actually use. AI project failure, in practice, usually looks less like a broken algorithm and more like a program that ran out of momentum before it reached production. The pattern repeats often enough across industries that it is worth asking what actually goes wrong, and why the same mistakes keep happening even as the tooling keeps improving.
ICANIO’s AI/ML Center of Excellence works with enterprises to close the gap between a working prototype and a system that survives contact with production data, real users, and regulatory scrutiny, drawing on delivery experience across the USA, the UK, Germany, Australia, and Malaysia. The patterns below are the ones that show up most often, and the fixes are less about better models and more about better engineering discipline.
Ask why an AI project failed and the honest answer, more often than not, starts with the data. A model trained on a clean, curated dataset can look excellent in a proof of concept and then fall apart once it meets the real thing: customer records split across three systems, sensor data with gaps no one flagged, labels that mean something different to every team that touched them. None of this shows up until the model is asked to run on live traffic instead of a sample someone hand-picked for the demo.
The deeper issue is usually that no one owned data quality as a deliverable in its own right. It is a less exciting phase of the work than building the model itself, but skipping it is one of the more reliable ways to guarantee failure once the system leaves the lab. Enterprises that treat a data audit as a prerequisite, not a formality, tend to catch these problems while they are still cheap to fix.
Infrastructure follows a similar pattern. Many IT environments were built for transactional workloads, not for the compute demands of model training and inference at scale, and teams that discover this only after a pilot succeeds end up rebuilding the foundation mid-project. A basic inventory of where the data lives, who owns each source, and how often it changes catches most of the problems that later get blamed on the model.
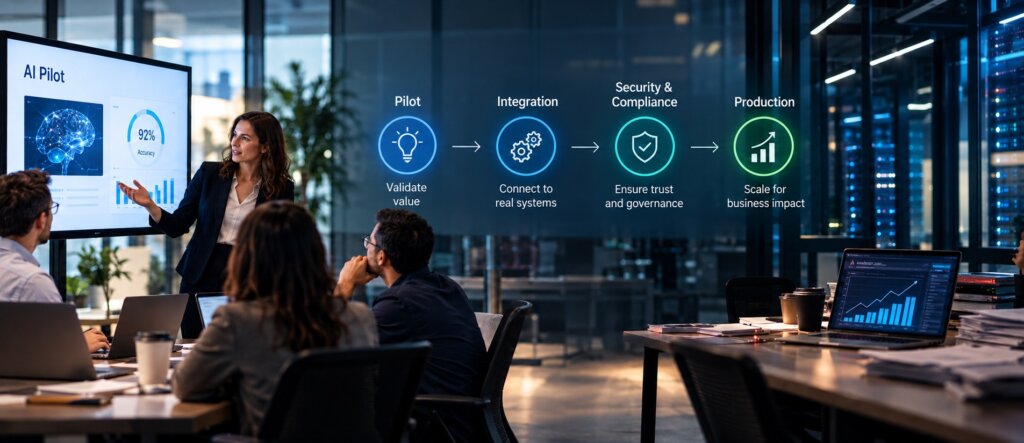
A large share of machine learning pilots never make it past the pilot stage, and the reason is rarely the model’s accuracy. Getting from pilot to production asks for things a pilot was never built to handle: integration with existing systems, a security review, monitoring that can tell you when the model starts drifting, and a plan for what happens if it gets something wrong in front of a customer. A notebook environment simply does not test for any of this.
Enterprises that treat the pilot as a finish line, rather than the first phase of a longer build, are the ones most likely to watch a promising initiative quietly stall. ICANIO’s product engineering teams have rebuilt more than one pilot-stage model from the ground up as a production service, with proper testing and observability included from the start, because the original plan never accounted for what production actually required. Budgeting for that second phase up front, rather than treating it as scope creep, is often the difference between a model that ships and one that sits in a repository.
This gap tends to be widest in regulated sectors, where a production system has to satisfy audit and compliance requirements a pilot never faced. Enterprises that build this expectation into the project plan from day one, rather than discovering it midway through deployment, spend far less time rebuilding what already looked finished. It also helps to be honest about timelines before the project starts: a pilot that took six weeks to build does not mean production readiness takes six weeks too, because it is solving a genuinely different problem.
Ask a room full of stakeholders who is accountable when a production model makes a bad call, and you will often get silence. That silence is where trouble quietly takes root. Without a named owner, there is no clear process for reviewing an unexpected output, escalating it, or deciding whether the model needs retraining, and the ambiguity gets more expensive the longer a system runs unsupervised.
This is especially costly in regulated environments. Financial services and manufacturing firms in the UK and Germany face real scrutiny over automated decisions, and a governance policy that only exists on paper does not hold up under that scrutiny. The fix is not complicated: one accountable owner per production model, a documented escalation path, and a habit of checking whether training data still reflects the population the model actually serves.
Enterprises that get this wrong tend to share a specific pattern: the business owner of the model and its technical owner were never the same person, and neither one felt responsible once the system reached a customer. Naming a single accountable owner before launch, not after the first incident, is the clearest way to prevent this from happening. A simple audit trail helps too. If a model’s decision can be traced back to the data and logic that produced it, disputes get resolved in minutes instead of becoming a weeks-long investigation that erodes confidence in the whole program.
A surprising number of implementation problems have nothing to do with the model and everything to do with who is around to keep it running. Data science teams are built to develop models; the machine learning engineering and platform operations skills needed to deploy and monitor those models in production are a separate discipline, and many organizations only discover the gap after the model is already live and something breaks with no one on call who understands it.
Change management is the other half of this. A model that changes how people work needs training, honest communication about what it does and does not decide, and a way for employees to flag outputs that look wrong. Skip this, and adoption stalls even when the model itself performs well, because the people who were supposed to use it never trusted it. ICANIO’s support engagements in Australia and Malaysia are frequently brought in for exactly this reason: closing an adoption gap that opened well after the technical build was finished.
Pairing every data science hire with a machine learning engineer from the outset addresses a good share of this before it surfaces. It is worth saying plainly: a technically excellent model that no one on the operations side understands is still a liability, no matter how well it scored in testing.
A polished sales demo is not evidence that a platform will work on your data. It is evidence that it works on the vendor’s data. Enterprises that skip a proof of concept against their own production-representative data, and rely instead on the demo, tend to discover the gap only after signing a long-term contract, when the integration friction and format lock-in are already expensive to unwind.
Most of what goes wrong after a bad vendor choice is not about the model’s accuracy; it is about flexibility. Organizations have increasingly favored platforms that avoid locking data into a proprietary format, including low-code and no-code tooling that can adapt as requirements change, over rigid products that need a full rebuild the moment the business shifts direction. The cheapest way to test any of this is to insist on a short, paid proof of concept against real data before committing to a multi-year contract. Vendors confident in their product rarely object, and the ones that do are telling you something worth hearing.
A governance framework is only useful if people actually follow it, which means it needs to be simple enough to survive contact with a busy team. The essentials are narrow: someone approves a model before it reaches production, someone monitors how it performs over time, and there is a clear trigger for retraining or pulling it back. More enterprises are formalizing this now, less because of appetite and more because regulators are starting to expect it.
Most enterprises that get this right start with one high-risk model, prove the process works, and expand it rather than trying to govern every system at once. That incremental approach lets governance mature alongside the AI program itself, instead of being bolted on all at once after something has already gone wrong and trust needs rebuilding. A structure built this way also tends to catch the early signs of trouble, model drift, rising override rates, unexplained decisions, long before they turn into a visible incident.
Data quality and infrastructure gaps top the list. Models that perform well on curated data often struggle once connected to messy, real production data. Investing in data architecture before model development tends to produce a much smoother path to production later on.
Pilots are usually built to prove technical feasibility, not to handle integration, security review, or ongoing monitoring. The gap between a notebook and a live system is easy to underestimate, and it is one of the clearest reasons a pilot that looked entirely successful never ships.
It varies by industry and regulatory context, but enterprises should expect a distinct phase for integration, security review, and monitoring setup rather than a quick handoff. Rushing this stage is one of the more common causes of a rocky rollout, and a phased approach with clear checkpoints tends to reduce the risk.
At minimum, clear ownership for model approval, ongoing performance monitoring, and a defined trigger for retraining or rollback. Data lineage documentation matters too, since it lets a team trace which data shaped a disputed decision.
Yes. Data quality, governance, and change management problems do not scale down with the size of the initiative. A small pilot without monitoring or a clear escalation path is just as exposed as a large, multi-region rollout.

ICANIO’s engineering team offers a no-obligation discovery call to look at what you’re dealing with, give you a straight read on the technical feasibility, and outline a delivery plan suited to your organisation’s scale, compliance environment, and budget.
From bold ideas to breakthrough execution our case studies showcase how we transform business challenges into innovation-led success stories.
ICANIO built an AI-powered healthcare record digitization platform that cut manual data entry by 60% and improved patient record accessibility 4x.
ICANIO built an AI-powered healthcare record digitization platform that cut manual data entry by 60% and improved patient record accessibility 4x.

ICANIO built a digital healthcare platform integrating patient records, telemedicine, EHR, billing, wearables, and AI insights, reducing administrative workload by 40% and improvin

ICANIO built a healthcare backend engineering platform that delivered services 2x faster, reduced operational risk by 30%, and improved scalability, reliability, and integration.
ICANIO built an AI-powered healthcare record digitization platform that cut manual data entry by 60% and improved patient record accessibility 4x.

ICANIO built a multi-tenant LLM fine-tuning pipeline on Azure OpenAI with isolated client models, automated DeepEval quality gates, MLflow tracking, and complete training lineage.
Quick Links
Careers
Internship
Contact Sales
© 2025
Icanio - All rights reserved.
